A website can appear old, take time to load, use an outdated theme, and still do pretty well in search results. This is one of the things you find out after spending a lot of time working with websites. The person who owns the website looks at the design and wants to change it; the developer looks at the old code, extra plugins, a difficult page builder and years of little fixes. Everyone agrees that the new website should be faster, more organized, easier to handle and better on phones.
Then the redesigned site goes live. It looks better, PageSpeed improves, the CMS is easier to use, and nothing appears to be broken. Yet several weeks later, organic traffic may start falling. The redesign itself is rarely the problem. The problem is that while rebuilding the website, the team also changed things Google had already spent years understanding.
An Old Website Is Not an Empty Website
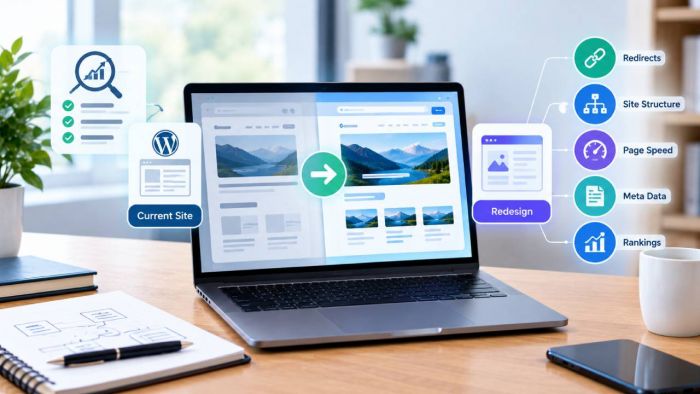
For us, no redesign or major rebuild begins without an audit of the existing website. When the audit shows that a feature, a section, a page or a content element on the website is working well, we do not remove that element just because the website is being rebuilt. First, we try to understand what value that element gives the website, how much of that value should stay, and how that element should exist in the new version of the website.
Old URLs on the website may look unattractive. The structure of the website may be inconsistent. Some service pages may sit three levels deep while others are right under the domain. Blog categories may have changed several times. From a development view, rebuilding everything around a new structure on the website feels logical. From an SEO view, however, the existing website is not a blank sheet of paper. Some of those URLs may already have backlinks. Some pages may rank for queries that nobody is actively monitoring. A weak-looking service page may have accumulated years of search history and visibility.
The first question is therefore not “What can we rebuild?” It is “What is already working, and how do we keep it working?”
Search Console Comes First
When I start an SEO audit, I normally begin with Google Search Console. It may have fewer features than dedicated SEO platforms, but it gives me the essential information I need to form a first opinion about the site, so for me it is the baseline. I look at which pages receive impressions and clicks, which queries create visibility, whether Google has started preferring another page for a query, and whether sections that nobody considers important anymore are still bringing organic traffic.
I look at where the real questions are, and then I use the tool that matches the task. Screaming Frog is great when I need to check the technical setup closely. Ahrefs or Semrush come in handy for backlinks, keywords, competitors and keeping track of things over time. I don’t think it’s helpful to open every SEO tool at once just because it’s there.
Search Console tells me where to look. The other tools help me look deeper.
A crawl is really important before a redesign because it shows things that the WordPress admin area does not show. It finds redirects that are left over from previous changes, issues with canonical tags, pages that are still linked inside the site, metadata problems, language versions, and URLs that the site owner may have forgotten about. This gives us a starting point before we begin making any changes.
Sometimes Fewer Pages Are Better
If a page has no traffic and has clearly lost its value, I have no problem removing it. If another page covers the same problem more completely, however, I normally redirect the old URL there rather than simply make it disappear.
A more difficult situation occurs when a site has tried too hard to strengthen one topic by publishing many articles about essentially the same thing. We have seen this on medical projects in particular. On one site, there were dozens of articles discussing variations of the same headache-related topic. The intention was understandable — cover the subject more completely — but the result was the opposite: the pages started competing with one another.
In cases like this, we first determine which page is the most relevant to the search intent we actually want to target. Then we look at the page’s existing traffic, rankings, links and overall value. That page becomes the main page and can be rewritten or expanded so that it answers the search query as completely as possible. The remaining pages need either a clearly different semantic focus or, if they have little value of their own, they can be removed and redirected to the stronger page. By doing this, we make sure that the best page speaks directly to what people are looking for.
More content is not always more authority. Sometimes it is simply more competition inside your own website.
Do Not Change a URL Just Because It Is Not Perfect
I don't change a URL just because I can make it look cleaner. If the current address is a little off but the page already gets traffic, has good rankings or has backlinks, I usually keep it as it is. There's no reward for having the perfect URL structure.
The situation changes when the URL no longer reflects what the page is really about. This may happen when the main search intent changes or when an article is substantially rebuilt around a different topic. In that case, preserving the old URL purely because it has history may no longer be the best decision. I would rather change the address so that it clearly matches the new subject and then redirect the old URL properly.
For me, the distinction is simple: if the URL is merely untidy, keep it. If it has become misleading, change it deliberately.
A redesign already introduces enough variables. There is little reason to add hundreds of unnecessary URL changes just because the new structure looks more elegant on paper. Google’s own site migration documentation also emphasizes careful URL mapping, permanent redirects, internal-link updates, and post-launch monitoring when addresses do change.
Redirect Chains Grow With the Website
A successful website still needs to be audited from time to time, and redirect chains are a good example of why. A site may begin with one structure, change several years later because the business changes, and then be rebuilt again. New service categories appear, old pages are merged, and articles are repositioned around different topics. It is not always possible, or even sensible, to preserve every URL exactly as it was.
After several such changes, an old address may redirect to a newer one, which then redirects somewhere else. That is how two-step and three-step chains appear. We recently found exactly this situation while auditing our own studio website. Nothing was visibly broken and the final pages opened normally, but the crawl showed that some old URLs were passing through two redirects because a previous redirect had remained in place after another URL change.
The solution itself was simple: point the oldest URL directly to the current destination. The more important lesson is that these chains rarely appear all at once.
Redirect chains usually accumulate with the history of the website.
Whenever I find more than one redirect in a chain, I prefer to simplify it. Otherwise, the next redesign may add another layer, and several years later nobody remembers why the chain exists in the first place.
I Prefer to Keep 404 Noise Low
If a page disappears, I normally try to redirect it to another page covering a closely related topic. There is also a practical reason for this that has little to do with theoretical SEO rules: we do not rely only on manual audits, because sites are also monitored through Ahrefs, Semrush, and other tools.
When a new 404 appears, I want to notice it and understand why it appeared. If a site already contains hundreds of 404 URLs that everyone has learned to ignore, a genuinely new problem can easily disappear inside that noise. A clean audit is easier to monitor than an audit full of old 404 errors that everyone has stopped noticing.
This does not mean that every deleted URL should be forced somewhere irrelevant. A redirect still needs to make sense for the user. But where a meaningful replacement exists, I prefer to use it. Redirects are therefore useful not only for preserving old traffic and links, but also for keeping technical monitoring understandable.
Google Does Not Always Choose the Page We Planned
Another common problem begins with an attempt to strengthen a topic by publishing several articles around it. The first page may be prepared very carefully: the semantics are researched, the target query is defined, and the content is written with SEO in mind. Then the client or site owner decides that more content on the same subject must be better and starts publishing additional articles that cover similar questions.
Now things get more unpredictable.
We can study the semantics carefully, but we cannot know for sure which page Google will associate with a query.
There is always a bit of what I call “Google shamanism”.
A secondary article may contain one explanation, phrase, or semantic angle that Google considers a better match for the query. Suddenly that article starts ranking ahead of the page we originally prepared as the main landing page, even though from an SEO specialist’s point of view the main page may be better structured, more complete, and much more deliberately optimized.
When this happens, I do not simply accept the result. I compare both pages. I look at their traffic, their rankings, the links that point to them, the main topics each page covers and the real search intent behind each page. Then I decide which page should become the main page. The other page needs a clearly different purpose or should be merged into the stronger page. This is why checking the search results before making major changes to an already-ranking page matters so much: the search results sometimes reveal something about our own website that the site structure does not.
Canonical Problems Are Easy to Miss
I think canonical problems are dangerous because a page can look completely normal. The page opens correctly, the content is present and the navigation works, but the canonical tag may still point to another address. This can happen after a migration, after a template change, after replacing an SEO plugin or after an update to a multilingual setup.
That is why I prefer to check canonical tags as part of the crawl instead of trusting what I see in the browser. What matters is consistency: the URL in the sitemap, the URL linked internally and the URL declared as canonical should not contradict each other without a good reason.
On a small site, checking several important pages manually may be enough to discover a problem. On a larger WordPress site with categories, filters, translated pages, templates, and plugins generating URLs automatically, crawling is much safer. This is also where a technical SEO checklist becomes useful — not because every warning from a crawler needs to be “fixed,” but because one small template error can quietly repeat itself across hundreds of pages.
Multilingual WordPress Can Become a Compatibility Problem
Multilingual WordPress sites need care when they get redesigned because just having a language switcher that works doesn't mean everything else is right. One older multilingual project we take care of still uses qTranslate-XT together with Yoast SEO, ACF and a custom theme. The site functions, but it doesn't function cleanly.
For example, when all three language versions of a page are saved at once, the Ukrainian URL slug can become corrupted with fragments from the other language versions. The workaround is manual: I clean the slug, save the Ukrainian version first, and only then add and save the Russian and English versions. Only after that does the Ukrainian URL remain correct.
We have seen similar conflicts in metadata. The visible English page may look perfectly English while an SEO field is already pulling content from another language version. From the visitor’s point of view, the site works; from the crawler’s point of view, something else may be happening.
In this case, I do not think there is much value in blaming one individual plugin. The real problem is the interaction between several old and new components that were never designed to work together indefinitely. There is also a practical limit to how far such a system can be modernized: replacing one of the core multilingual components or updating the old custom theme may break something else. At some point, fixing individual incompatibilities stops being maintenance and becomes an argument for rebuilding the site properly.
Sometimes the SEO problem is not a bad setting. It is an old stack that has simply reached the limit of how safely it can be maintained.
A Live Website Can Still Be Invisible to Google
I have seen this error many times. Developers properly stop a staging or development site from being indexed while the work is still happening. Then the completed website is put live, and someone forgets to remove the noindex tag.
To the client, everything seems fine: the site is up, pages load properly, the navigation works and the forms can be filled out. Google might still be getting a message that says not to index the site. A few weeks later, the owner starts wondering why the new website isn't showing up in search results at all, and the reason can be very simple.
That is why checking whether the site can be indexed is one of the first things I do after a launch. I do not assume that just because a website is published it is automatically able to be indexed.
A site can be completely functional for users and almost invisible to Google at the same time.
After a launch, I like to look at the production environment again: noindex, robots.txt, sitemap availability, canonical tags and WordPress search visibility settings. Staging restrictions are helpful; staging restrictions left on the live site are not.
Changing Site Structure Creates Two Problems at Once
Internal linking is another strong argument for preserving the existing site structure whenever reasonably possible. A major URL restructuring normally creates two related problems. The first is obvious: if old URLs are not mapped carefully, many pages that search engines and external websites already know suddenly stop existing, which produces 404 errors and can lead to a temporary loss of visibility.
The second problem is easier to overlook because internal links stop working too. Navigation menus are usually not the biggest concern: they are visible, centrally managed, and rebuilt as part of the redesign. Contextual links are different. Links inside old articles, service pages, case studies, category descriptions, and other content are much easier to miss. That is why preserving the URL structure can sometimes be more valuable than creating a new URL structure that is only theoretically perfect.
If the structure really needs to change, the redirect map must be prepared carefully. The goal is not only to reduce 404 errors, but also to keep the connections that the website has built between its pages over the years. When redirects work correctly, I still prefer to update important internal links so that they point directly to the final URL.
A redesign does not only change pages. It can also break the connections between them.
FirmSuggest discusses a related technical principle in its article about Node.js hosting, crawlability, and rendering: what users see in the browser and what search engines can reliably access are not always the same thing. Internal linking deserves the same kind of technical attention.
Metadata Is Easy to Lose Because Nobody Sees It
A redesign can preserve every visible paragraph on a page and still lose its title, description, structured data, or other SEO elements. This happens more often on older WordPress sites because SEO information is not always stored in one place: part may live in Yoast or another SEO plugin, some values may be stored through ACF, a theme may generate other elements directly in a template, and a multilingual plugin may influence all of them.
Then an import script or new theme transfers the visible content perfectly while part of the SEO layer disappears. Titles deserve particular care on pages that already rank because a new title may sound better to the marketing team while removing wording that Google has already associated with useful searches.
This does not mean old metadata should never change. It means the change should be intentional. There is a big difference between improving a title because we have analysed the current search results and replacing it simply because nobody realised the old value had not been migrated.
Analytics Must Survive the Redesign Too
Organic visibility is only part of the migration. A new website can launch with correct redirects and still make marketing performance difficult to evaluate if analytics and conversion tracking do not survive the rebuild.
GA4 may continue collecting page views while important events disappear. A new form replaces the old one, so the submission event no longer fires; phone links use different markup; a new checkout changes the purchase event; cookie consent affects tags; or Google Ads continues optimizing against a conversion action that no longer represents the same behaviour. The site works, but the measurement no longer does.
Before launch, I prefer to document the actions that matter to the business and then test them individually on the new website: form submissions, phone clicks, email clicks, checkout, purchase, or whatever is actually important for that project. Seeing visitors in GA4 is not enough to conclude that analytics survived the migration correctly.
This becomes especially important when a redesign and an advertising campaign are running at the same time. If reported conversions suddenly fall, we need to know whether the business changed, the advertising changed, or simply the tracking changed.
Launch Day Is the Beginning of the Check
After a planned redesign, I crawl the site again. I examine status codes, redirect destinations, canonicals, indexability, sitemap URLs, hreflang where it applies, broken links on the site, and any unexpected metadata changes. Then I return to Search Console.
Not every ranking fluctuation after a redesign means something has gone wrong. What interests me more is the pattern: are the old URLs being replaced by the intended new ones, are new 404s appearing, have impressions shifted between pages, did an important landing page disappear from search, or did Google start ranking another page for a query we were targeting elsewhere?
The crawl made before the redesign becomes extremely useful at this point because it gives us something concrete to compare against. Without that baseline, several weeks after launch you may know that something changed but no longer remember exactly what the old site looked like.
A Full Rebuild Still Has to Be Worth It
I am not against rebuilding websites from scratch. Sometimes rebuilding a website is clearly the right decision. If a complete rebuild can significantly improve the user experience, make the website easier to use and manage, simplify important actions, improve performance and ultimately help the business turn more visitors into customers, then the work can be justified.
A full rebuild costs time and introduces migration risk, so I would not rebuild a working website simply because a newer theme, cleaner architecture or more elegant technical solution is available. The improvement needs to be meaningful enough to justify replacing what already works.
If rebuilding the website will clearly make life easier for both the business and its customers, I will rebuild it. If the benefit is mostly technical elegance, I would rather preserve the working parts of the website and improve them selectively.
A ten-year-old website can contain bad code and good SEO. An awkward URL can still have backlinks. An old page can still be the answer to a search query. A multilingual website can look fine while its metadata is quietly breaking underneath.
The goal of a redesign is not to preserve everything. The goal is to separate technical debt from accumulated value: replace what genuinely needs replacing, keep what still works, and when something important has to change, make sure the value has somewhere to go.
A redesign should earn the right to replace what already works.
About the author
Bohdan Prytulyak is the founder of PBB Design Studio and has more than 20 years of experience working with websites. His current work focuses on WordPress development, technical SEO, website performance, and digital marketing.
Post Comment
Be the first to post comment!